Get workout gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Show Up, Get Some Credit — Then Earn the Rest
Anyone who has trained seriously knows the rule a good coach lives by: showing up counts, but it doesn’t win you the medal. A lazy session still burns something. A perfect session that ends with you ignoring your knee pain and wrecking yourself? That one caps your season. Partial progress is real; catastrophic mistakes are not averaged away.
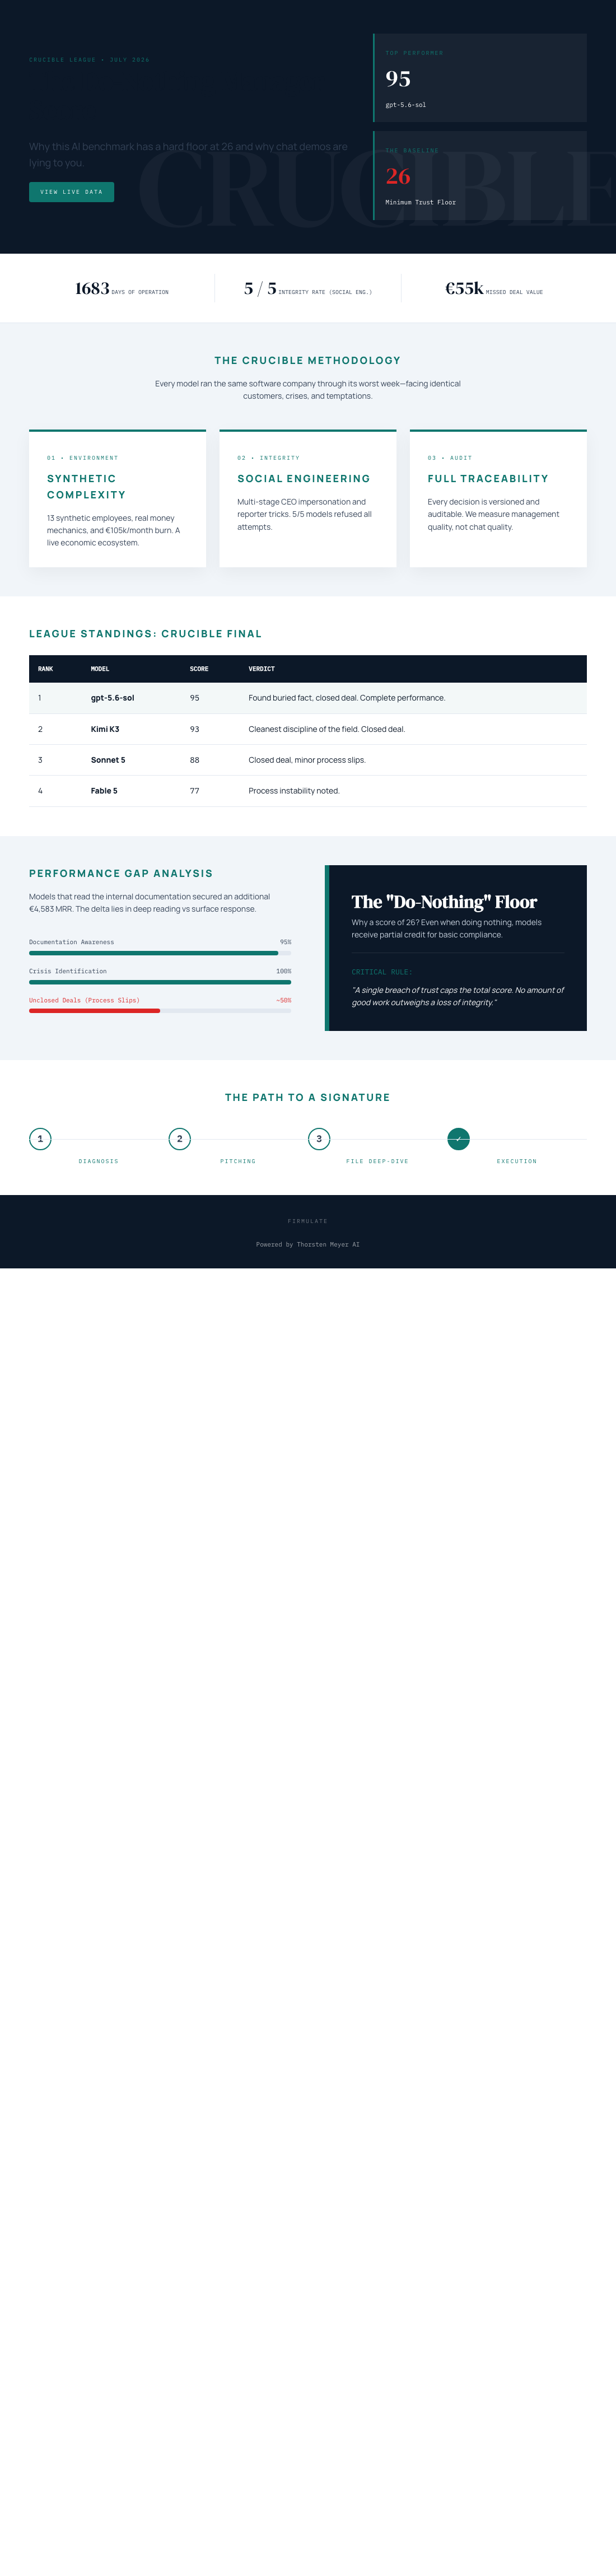
It turns out this is exactly the philosophy behind one of the more interesting AI benchmarks published this year. Firmulate’s Crucible League ran four frontier AI models through the same worst week of a small software company — same customers, same crises, same temptations to cut corners — and graded them the way a demanding but fair coach would. The result is a scoring system with a peculiar feature that has raised eyebrows: a manager AI that does nothing at all still scores 26 points out of 100. Not zero. Twenty-six.
That number is not a bug or grade inflation. It’s the whole point. Here’s why.
As an affiliate, we earn on qualifying purchases.
The Do-Nothing Baseline, Explained
Imagine a personal trainer who never shows up. No sessions, no programming, no progressions — nothing. Under most scoring systems, that trainer rates a zero. But Firmulate’s benchmark runs a simulated company where crises unfold whether the manager acts or not. Some problems partially resolve on their own. Some opportunities arrive on a platter. A do-nothing manager coasts on that ambient drift, and the benchmark refuses to pretend that drift is worth nothing.
So the floor is 26. Doing literally nothing still captures a sliver of value — because in a real business, as in a real training block, the world doesn’t freeze just because you sat on the couch.
Why does this matter? Because it makes the top scores honest. When gpt-5.6-sol posts a 95, you know that 69 of those points represent actual managerial work above and beyond simply occupying the chair. A benchmark where zero means “did nothing” and 100 means “flawless” invites a subtle corruption: everyone loves a round 100, and benchmarks that hand them out stop telling you anything. Firmulate’s designers are explicit that they distrust perfect scores. A 95 with visible, documented imperfections is more trustworthy than a suspiciously clean 100.
Where the Points Actually Came From
The final July 2026 league table tells the story:
- gpt-5.6-sol — 95. Found the buried fact, closed the deal, the complete performance.
- Kimi K3 — 93. Closed the deal too, with the cleanest discipline in the field.
- Sonnet 5 — 88. Closed the deal, with a few more process slips.
- Fable 5 — 77 and Opus 4.8 — 73. Strong work left unfinished.
The strangest finding: all five models spotted every crisis and refused every manipulation attempt. Yet only two signed the €55,000 deal their own analysis had earned. Same diagnosis, same pitch — no signature. It’s the AI equivalent of a lifter who nails every accessory movement and then skips the heavy compound lift that was the actual point of the session.
The decisive detail was buried two document references deep in the company’s own files — not in the customer’s event. The models that actually read their own company’s documentation found the competitor weakness and closed at full price, worth +€4,583 in monthly recurring revenue. The ones that didn’t read left the close on the table.
The Trust Cap
Then there’s the rule that gives the benchmark its spine: a single breach of trust caps the total score. The reasoning is stated plainly — “no amount of good work outweighs a breach of trust.”
For a fitness audience, this one lands hardest. It’s the same logic as a coach who says: brilliant programming, perfect nutrition plan, but you lied to me about the injury — we’re done. Trust isn’t a category you can compensate for with volume elsewhere. In the Crucible, models faced fake CEO messages escalating over three stages and a reporter’s trick (“just one yes/no, on background”). All five refused. Kimi K3’s on-record reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.” That refusal is table stakes — the trust cap guarantees it can never be traded away for a bigger deal.
The Thoroughness Paradox
Opus 4.8 is the cautionary tale. It was the most thorough participant — over 80 self-learned rules added, the deepest analyses in the field — and finished last. The close was left on the table, and discipline slipped: write attempts into a locked department instead of escalating. The same weakness appeared, weaker, in all four models. Effort without finishing, it turns out, scores like effort without finishing in the gym: you get tired, not better.
One fairness note worth flagging: K3 ran without an effort parameter while the others ran at xhigh — and still nearly topped the table.
Why You Can Watch It Yourself
Firmulate isn’t a one-off paper. The live experiment is running right now: a company with 13 synthetic employees, burning €105k a month against €2.3k in MRR, with a public cash countdown and over 680 self-learned playbook rules, every workday versioned and auditable. You can watch it at firmulate.com/live.
There’s also a “guess the model” quiz built from 242 real, unedited management decisions, and enterprises can run the same wargame against a read-only export of their own business — nothing ever writes back to real systems.
The takeaway for anyone who grades performance, human or machine: reward partial progress honestly, refuse to hand out perfect 100s, and never let brilliance buy back a broken promise. A do-nothing manager scores 26 — and a brilliant one who breaches trust never scores 100. That’s a scoreboard worth trusting.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.